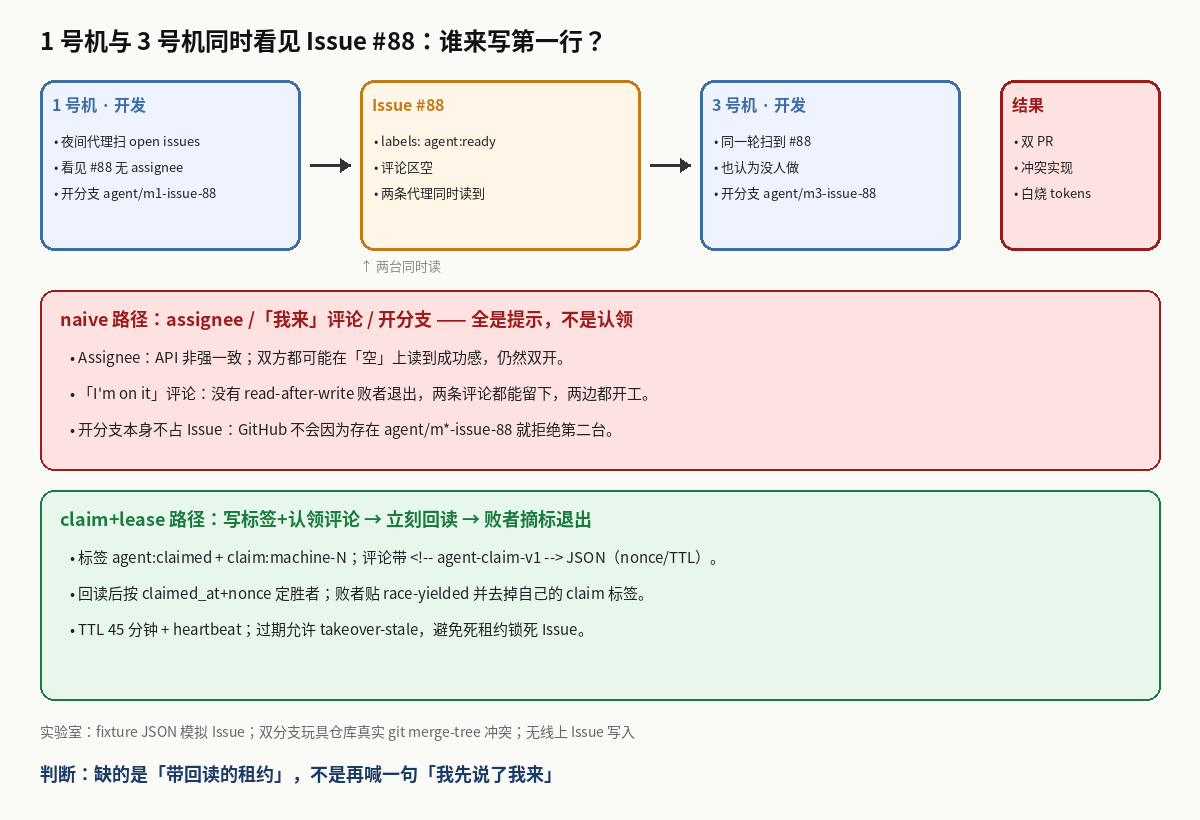
凌晨一点零四分,Issue #88 还挂着 agent:ready。标题很短:member discount applied twice on renewal。没有 assignee,评论区空,也没有任何 agent/*-issue-88 分支。1 号机上的代理刚扫完 open issues,把它排进今晚的队列。三分钟后,3 号机上的代理跑完同一份脚本,得出同一个结论:没人做,我来。
早晨七点,Tech Lead 在 4 号机打开 GitHub:PR #521 agent/m1-issue-88 和 PR #522 agent/m3-issue-88 并排躺着。两个实现改的是同一个 discount.py,一个做 10% 再 clamp,一个做固定减 ¥10。git merge-tree 直接报 changed in both。两台机器各烧掉大约半小时代理时间,产物却不能直接合——还要人来挑哪一版是对的业务语义。
三人、七台机:1–3 开发(代理高频开 PR),4–5 审查,6 Windows 验证,7 合并/运维。前几篇分别谈过审查租约、Windows 失败现场、隔夜 PR 分诊、WIP 移交。那些都假定已经有人合法地开了工。这篇只谈更早的一刀:两台开发机同时看见同一个 Issue 时,谁有权写下第一行代码。
这件事平时不容易被当成「故障」。PR 绿了也能合,冲突大不了 rebase,tokens 账单月底才刺眼。可一旦你让代理按小时扫 Issue,抢单从偶发变成稳态。1 号机和 3 号机没有仇,也没有同步时钟;它们只是共享同一个启发式,又共享同一个公开的 Issue 列表。启发式说「可以做」的瞬间,两边都会做。
我先把结论写在前面:Assignee、「I'm on it」评论、已经存在的分支名,全都只是提示,不是认领。 GitHub 标签写入也不是强顺序事务。你要的是带 TTL 的 claim+lease,并且写完必须回读——败者退出,胜者续租,死租约可被接管。没有败者协议的任何「我先说了」都是噪音。
下面是我在本机搭的实验:claim_issue.py 用本地 JSON fixture 模拟 Issue 的标签与评论;simulate_race.py 跑 40 个早市 × 双机竞态;玩具 git 仓库真实存在两条冲突分支。竞态数字全部来自 fixture 模拟,没有对真实远端 Issue 做写入。 协议脚本另提供 --live,只打印 gh 命令,默认不执行。
场景:同一张工单,两台机器
| 项 | 值 |
|---|---|
| Issue | #88 member discount applied twice on renewal |
| 初始标签 | agent:ready |
| 1 号机动作 | 开 agent/m1-issue-88,10% + clamp + round |
| 3 号机动作 | 开 agent/m3-issue-88,固定减 ¥10 |
| 早晨现场 | 双 PR;discount.py merge-tree 冲突 |
| 浪费 | 约 2 × 35 代理分钟(实验室按每次重复开工计) |
代理人很「诚实」:它按你写进 AGENTS.md 的启发式行动——没 assignee、没人评论「我来」、没有同名分支,就可以开工。问题不在启发式写错了,在这些信号从来就不是互斥锁。
再往下一层:即便你规定「看见别人的分支就别动」,夜间两台机器也可能在对方 git push 之前同时 git checkout -b。本地分支名不进 Issue API,远端分支要等 push 才可见。把「有没有分支」写成锁,等于把锁的可见性推迟到网络延迟之后——而竞态刚好发生在延迟里。
所以这篇不讨论怎么写更好的 prompt 让模型「更懂礼貌」。礼貌解决不了双读空。要解决的是:在 Issue 这个共享对象上,建立可检验的占用关系,并且让失败的占用方必须停手。
四种抢单办法
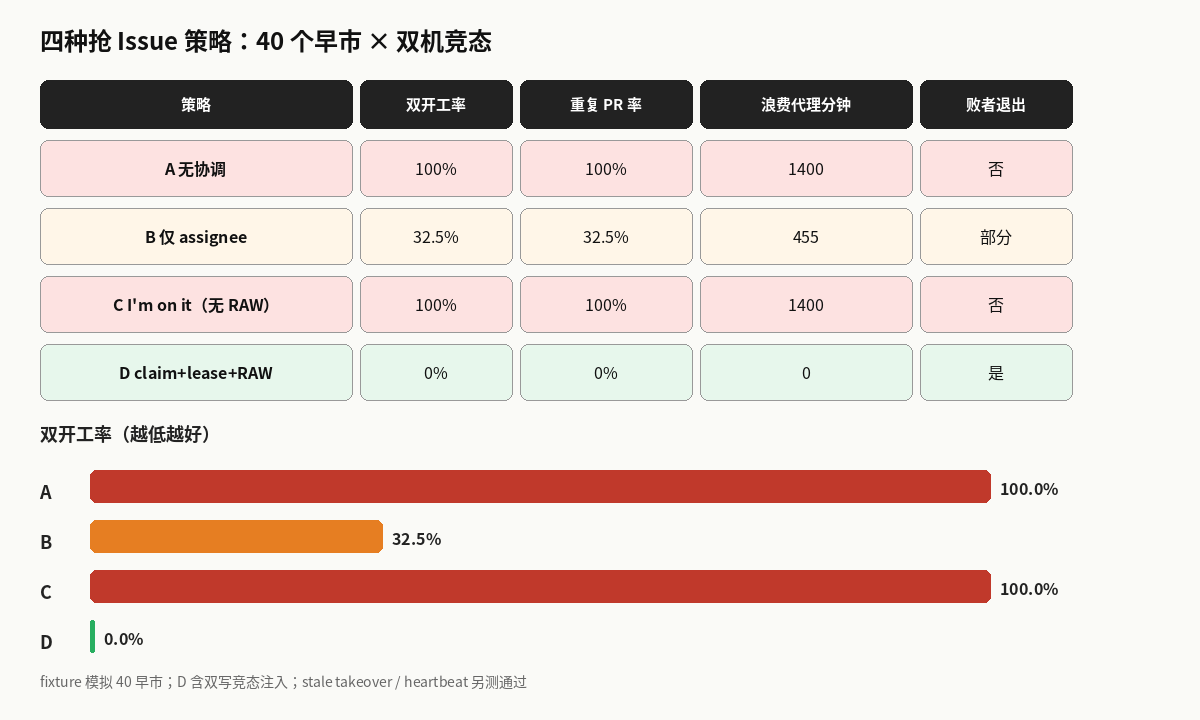
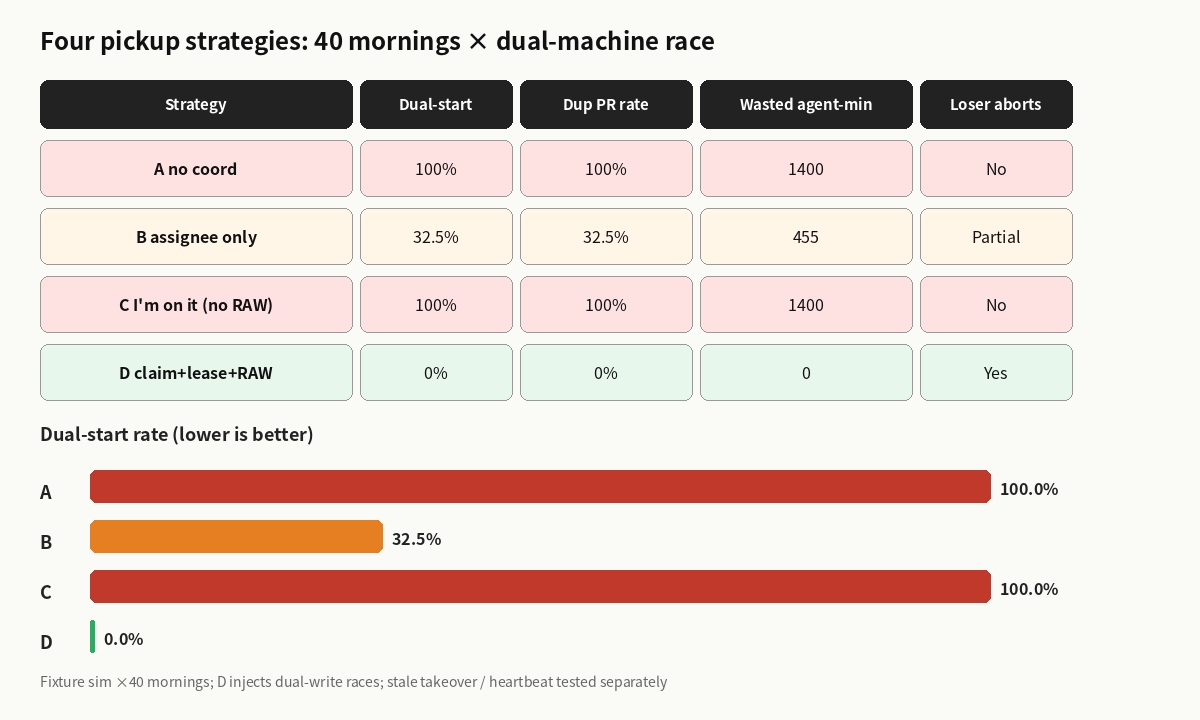
我让同一张 Issue #88 在四种策略下各过 40 个合成早市,两台机器几乎同时决定要不要开工。量四件事:双开工率、重复 PR 率、浪费的代理分钟、败者会不会退出。
| 策略 | 双开工率 | 重复 PR 率 | 浪费代理分钟(40 早市合计) | 败者退出 |
|---|---|---|---|---|
| A 无协调 | 100% | 100% | 1400 | 否 |
| B 仅 assignee | 32.5% | 32.5% | 455 | 部分 |
| C 「I'm on it」无回读 | 100% | 100% | 1400 | 否 |
| D claim+lease+RAW | 0% | 0% | 0 | 是 |
A:无协调——默认就是双开
两台机器看到同一快照,都开工。实验室里 40/40 早市双开,合计浪费 1400 代理分钟(按每次重复开工 35 分钟计)。这不是夸张的故障注入,这是「启发式说可以做」时的基线。
你会下意识觉得「怎么可能天天双开」。在人肉派单的时代确实少:人会在群里吼一声,或者看板把卡片拖走。代理没有群,看板卡片也不会自动变成 API 锁。它读 Issue 列表的方式,更像两个爬虫同时读同一张 RSS。A 策略的意义是标定天花板:如果你什么协议都不加,双开工率就是 100%。后面所有「改进」都要跟这个数比,而不是跟想象中的「偶尔撞车」比。
B:只靠 assignee——还会漏三成
「先 assignee 再写代码」听起来像锁。GitHub 的 assignee 更像最后写入的提示:在竞态窗口里,两边都可能先读到空列表,再各自以为自己写上了。我在 fixture 里给了 35% 的「双读空」窗口;40 早市里仍有 13 次双开工(32.5%),浪费 455 分钟。即便服务器最终只留下一个 assignee 名字,两边代理都已经开跑了——名字对了,活还是干重了。
Assignee 还有更软的问题:人或 bot 忘了取消、多人共账号、细粒度 token 根本没 Assignees 写权限。把它当唯一闸门,是把社会约定误当成协议。
另外,assignee 字段表达的是「谁负责」,不等于「谁正在写第一行」。4 号机审查的人也可以被 assign 去做跟进;7 号机运维可以被 assign 去做发布。字段被复用之后,开发代理更不能从「有 assignee」直接推导「我不该动」。认领协议需要一个只服务于开工权的名字空间——这也是为什么我用 claim:machine-N,而不是复用 assignee。
C:「I'm on it」——没有回读就等于没说
评论区留一句「我来」是团队里最常见的土办法。模拟里两台机器都先读到空评论,再都贴上「I'm on it」,再都开工。两条评论都在,没有人当败者。 双开工率回到 100%,浪费与 A 相同。
失败点不在「该不该评论」,在写完不回读、回读了也不按规则退出。提示写成了事实,事实却没有互斥语义。
我刻意把 C 做成「评论成功即开工」。有人会说:那我们规定必须回读啊。可以。可一旦你加上回读和败者退出,C 就不再是 C,它已经滑向 D——只不过 D 把字段、TTL、nonce、标签状态机一次性写死,避免每个代理用自然语言重新发明一遍「怎样算我输了」。
D:claim + lease + read-after-write
协议很短,短到可以贴进 AGENTS.md:
- 读标签:若已有活的
agent:claimed且租约未过期 → 拒绝。 - 写:加上
agent:claimed与claim:machine-N,去掉agent:ready;发一条带<!-- agent-claim-v1 -->的评论,JSON 里带machine_id / session_id / issue / claimed_at / expires_at / nonce。 - 立刻回读全部认领评论;按
claimed_at再nonce选出唯一胜者。 - 若自己不是胜者:去掉自己的
claim:machine-N,把评论改成race-yielded,停止开工。 - 持有期间每 ~30 分钟
heartbeat刷新expires_at(默认 TTL 45 分钟)。 - 放弃或做完:
release。发现过期死租约:takeover-stale后再 claim。
40 个早市里,我还故意注入了「双写」窗口——两边都通过「当前无活租约」检查、都写出评论——再各自做回读。结果:双开工 0%,重复 PR 0%,浪费 0。 败者每一次都 abort。另测:把 expires_at 拨到过去后,3 号机 takeover-stale 成功;heartbeat 能续租。这些在 fixture 上真实跑过。
有两个实现细节值得写进规范,而不是留在口头:
- 胜负键是
claimed_at+nonce,不是「谁的标签先出现在 UI」。 标签列表不保证你看到的顺序等于写入顺序;nonce 是代理本地生成的随机串,用来在同一秒的双写里打破平局。 - 败者必须留下
race-yielded痕迹。 只删标签不改评论,早上的人会看见两条「我已认领」的幽灵评论,反而更乱。屈服评论是审计线索,也是给下一个代理的信号。
协议脚本在 --fixture 模式下用单文件 JSON 模拟 Issue;--live 只打印等价的 gh issue edit / gh issue comment / 回读命令。实验室默认拒绝 --execute,避免有人把演练打到真实业务 Issue 上。
冲突的代价不只是「多开一个 PR」
玩具仓库里,master 上的 apply_discount 只是简单的 price * 0.9。1 号机改成 clamp + round + discount_code();3 号机改成固定减 ¥10 + member_tier()。对同一文件跑 git merge-tree,得到标准的 changed in both 冲突块。
这比「两个空 PR 标题撞车」更糟:审查机不能点一个 Approve 了事,必须先裁决业务语义——续费场景到底是比例折扣还是满减。代理不会自己开会。双开工的税,收在 4 号机的早上,也收在被烧掉的 tokens 里。
还有一种更隐蔽的税:测试套被两边各自「补强」。1 号机为 10% 路径加了 round 断言;3 号机为满减路径加了边界用例。表面上覆盖率都上升,主线合并时却要删掉一半测试,或者更糟——留下两套互相打架的断言,后续代理再改定价时会被两侧同时咬住。双开工不只浪费当下,还污染仓库的叙事。
机制:为什么「提示」扛不住并发
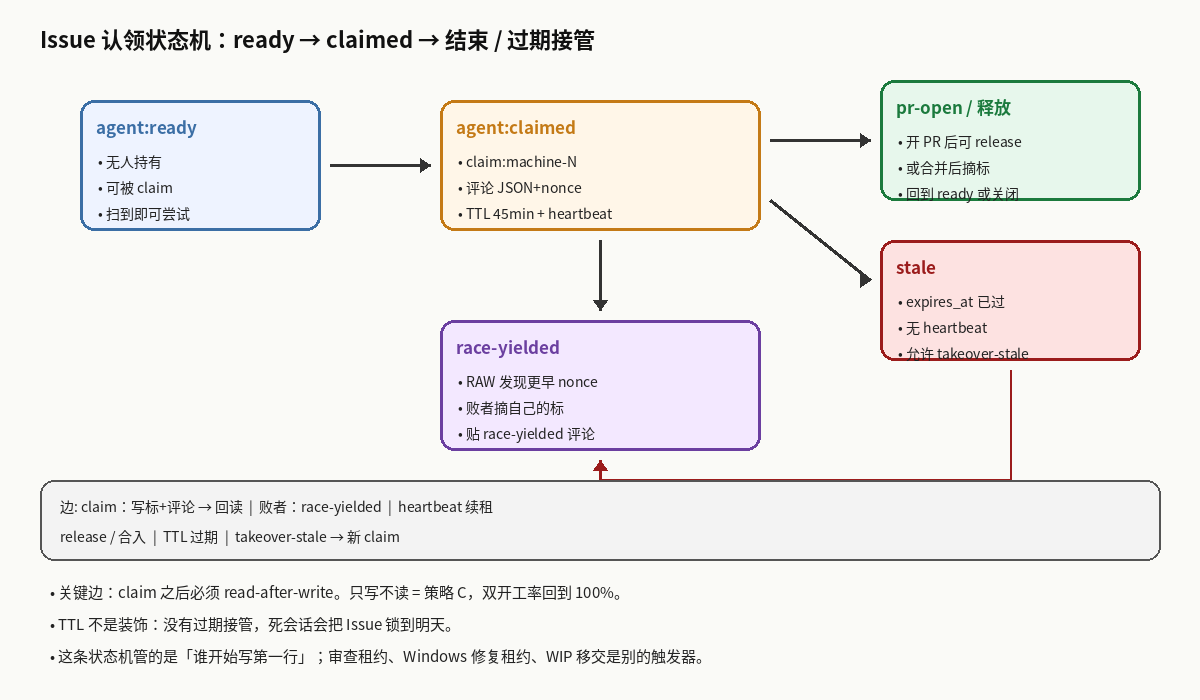
- GitHub Issue 不是分布式锁服务。 标签与评论是最终可见的对象,写与读之间没有你以为的事务边界。两台机器可以读到同一份「空」。
- Assignee / 口头认领 / 分支名都缺乏败者协议。 没有「发现别人更早 → 自己退出」的强制步骤,提示就只是提示。
- 代理会话是短命的。 没有 TTL 与 heartbeat,一台半夜断线的机器会把 Issue 锁到人来解;没有 stale takeover,租约比无协调更糟。
- read-after-write 是最小补丁。 你不需要外置 etcd。Issue 评论区当公告板就够——但必须:写完再读、按 nonce 定胜负、败者删除自己的租约痕迹。
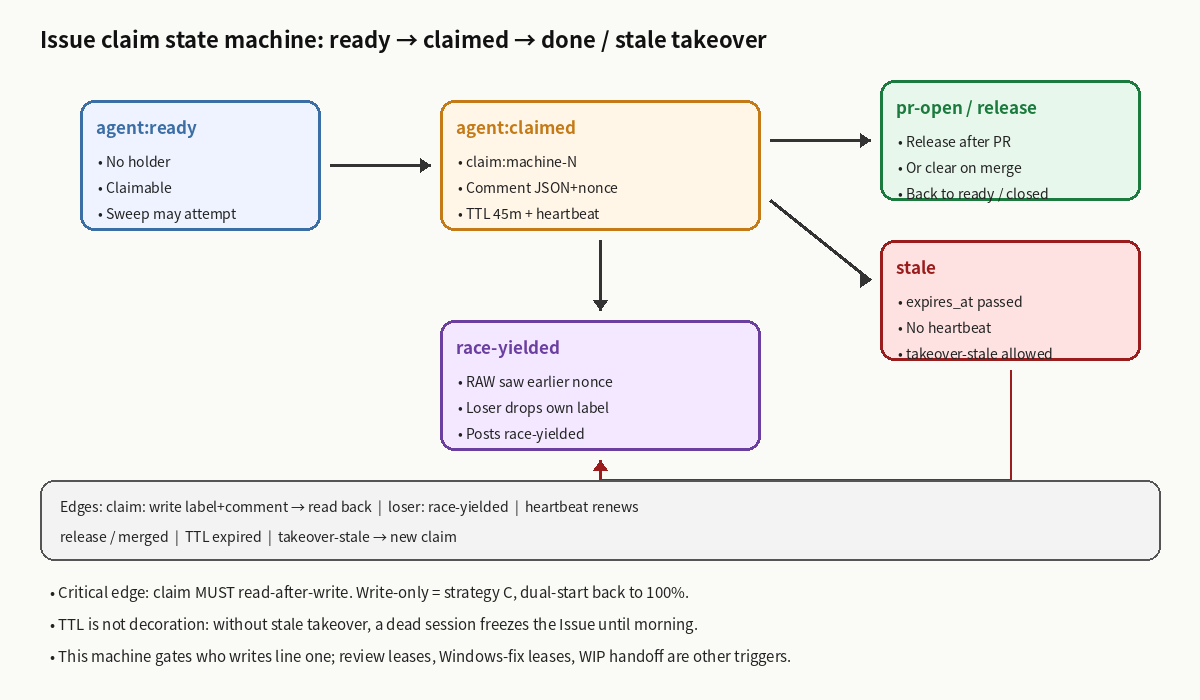
状态机可以画成:agent:ready →(claim+RAW)→ agent:claimed →(开 PR / release)结束;旁路是 race-yielded(败者)与 stale→takeover-stale。缺任何一条边,都会退回 A/C 的双开世界。
把「回读」从步骤里拿掉,D 会立刻退化成 C:两边都以为自己写上了唯一认领。把 TTL 拿掉,D 会退化成更糟的东西——死会话永久占坑,比双开还伤。把 race-yielded 拿掉,早上的分诊脚本无法区分「曾经输掉的尝试」和「仍然有效的租约」。四条边是最小闭环,不是为了画图好看。
代价与不适用
- 每次开工多两次 API 往返(写评论 + 回读)。相对半小时代理会话,可忽略。
- 要维护一组标签:
agent:ready/agent:claimed/claim:machine-N。kit 里有label_commands.sh。 - TTL 选太短:正常心跳抖动会误触发 takeover;太长:死会话占坑。45 分钟配 30 分钟心跳,是实验室默认,可按你们夜间会话长度改。
- 不必上这套时: 一人一机、Issue 本来就由人指派且从不并行扫、或者仓库一天开不了两张代理 PR。那时 assignee 约定就够。
- 解决不了的: 业务上本来就该两个人平行探索同一问题——那是显式的 spike fork,应该开子 Issue,而不是假装在抢同一张。
- 不是审查租约,也不是 Windows 修复租约,更不是 WIP 移交。 触发器不同:这里是「谁可以开始写」;那边是「谁接着改评论 / 谁去拉失败现场 / 谁接手未完成分支」。
- 标签爆炸风险: 每台开发机一个
claim:machine-N还好办;若你把会话 id 也做成标签,Issue 会变成垃圾场。会话放进评论 JSON,标签只保留机器维度。 - 权限: 执行 claim 的 token 需要 Issues 写权限,但不需要 Contents 写权限去直接推 main。认领与合码解耦,正好契合最小权限那一篇的方向。
和相邻文章的边界
- /changes-requested-dead-agent-session/:审查机点了 Request changes,开 PR 的会话已死——那是审查线程上的租约。本文的输入是一张还没人动的 Issue。
- /handoff-agent-task-between-machines/:WIP 从一台迁到另一台。本文假定两台都想从头开始,不是移交。
- /windows-ci-failure-back-to-linux-agent/:失败现场怎么回到 Linux 代理。租约对象是「修复权」,不是「Issue 开工权」。
- /overnight-agent-pr-morning-triage/:早晨怎么杀隔夜 PR。本文讨论的是为什么会一夜冒出两个撞车 PR。
- /parallel-agents-ports-databases/:端口与数据库抢占。那是运行时资源;这里是 Issue 语义资源。
明天就能抄的最小集
- 建标签:
agent:ready、agent:claimed、claim:machine-1..3(脚本在 kit)。 - 把
claim_issue.py放进仓库工具目录;AGENTS.md写明:先 claim 成功再开分支;ok: false就换下一张单。 - 认领评论必须带
<!-- agent-claim-v1 -->JSON;禁止只写「我来了」当锁。 - 默认 TTL 45 分钟;会话内 heartbeat;放弃必
release;过期用takeover-stale。 - 早上分诊时,看见双 PR 撞同一 Issue:先查有没有 claim 评论。没有的话,不是代理「太积极」,是协议没装。
落地顺序:先在一个玩具仓库用 --fixture 跑通 claim / 败者退出 / takeover;再 --live 打印 gh 命令,人工看一遍后接到真实 Issue。不要一上来就让七台机器写生产标签。
若你们已经有看板机器人把卡片状态同步到 Issue 标签,不要并行发明第二套「进行中」。要么让看板状态成为 claim 的唯一写入口(机器人代写 agent:claimed),要么关掉看板同步,只保留 claim 协议。两套「进行中」同时写,等于把竞态藏进同步延迟里——更难查。
诚实说明:什么跑过、什么没有
跑过(本机):
simulate_race.py:策略 A/B/C/D × 40 早市;headline:A/C 双开 100%,B 32.5%,D 0%;浪费分钟 1400 / 455 / 1400 / 0。claim_issue.py --fixture:claim 成功、第二台already_claimed、heartbeat、release、过期后takeover-stale。- 玩具 git:
agent/m1-issue-88与agent/m3-issue-88;git merge-tree对discount.py报changed in both。
没跑:
- 没有对
shuizhengqi1/pages或任何真实业务仓库的 Issue #88 做线上写入。 - 没有七机同时在线的集成测试;双写窗口是在 fixture 里注入的。
--live只打印gh命令,实验室默认不--execute。
Kit:two-agents-claim-same-issue-kit.tar.gz — claim_issue.py、simulate_race.py、results.json、AGENTS.md.snippet、label_commands.sh、玩具冲突快照。
今天最小的一步:下次再让代理扫 Issue,不要问「有没有人说我来」。问「这张单上有没有活的 agent:claimed,以及回读之后胜者是不是我」。如果答案是否,第一行代码就不该出现在你的工作区里。
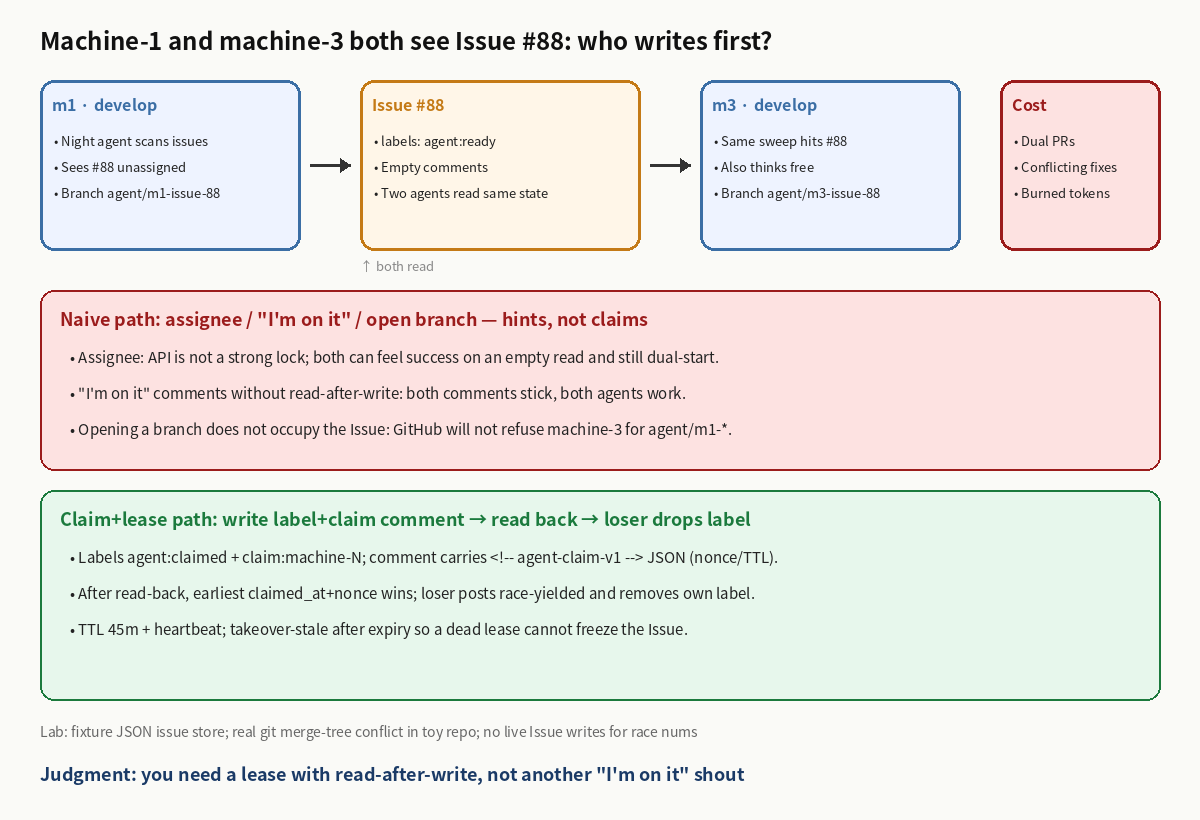
At 01:04, Issue #88 still wore agent:ready. Title: member discount applied twice on renewal. No assignee, empty comments, no agent/*-issue-88 branch. Machine-1's overnight agent swept open issues and queued it. Three minutes later machine-3's agent ran the same script and reached the same conclusion: nobody owns this — I'll take it.
At 07:00 the Tech Lead opened GitHub on machine-4: PR #521 agent/m1-issue-88 and PR #522 agent/m3-issue-88 side by side. Both touched discount.py — one 10%+clamp, one flat ¥10 off. git merge-tree reported changed in both. Each machine burned roughly half an hour of agent time; neither PR could merge cleanly until a human picked a business meaning.
Three people, seven machines: 1–3 develop (agents open PRs at high frequency), 4–5 review, 6 Windows validation, 7 merge/ops. Earlier posts covered review leases, Windows failure scenes, overnight PR triage, WIP handoff. Those assume someone already had the right to start. This post is one step earlier: when two develop machines see the same Issue, who may write the first line.
Lab on this box: claim_issue.py against a local JSON fixture mimicking labels+comments; simulate_race.py for 40 mornings × dual-machine races; a toy git repo with two conflicting branches. Race numbers are fixture simulation only — no writes to a real remote Issue. --live prints gh commands and does not execute them by default.
Scene: one ticket, two machines
| Item | Value |
|---|---|
| Issue | #88 member discount applied twice on renewal |
| Initial label | agent:ready |
| Machine-1 | Branch agent/m1-issue-88, 10% + clamp + round |
| Machine-3 | Branch agent/m3-issue-88, flat ¥10 off |
| Morning | Dual PRs; discount.py merge-tree conflict |
| Waste | ~2 × 35 agent-minutes per dual start (lab accounting) |
The agents are "honest": they follow heuristics in AGENTS.md — no assignee, no "I'm on it", no matching branch ⇒ start. The heuristics are not wrong as hints. They were never a mutex.
Four pickup strategies
Same Issue #88, four strategies, 40 synthetic mornings, two machines deciding nearly together. Metrics: dual-start rate, duplicate-PR rate, wasted agent-minutes, whether the loser aborts.
| Strategy | Dual-start | Dup PR | Wasted agent-min (40 mornings) | Loser aborts |
|---|---|---|---|---|
| A no coordination | 100% | 100% | 1400 | No |
| B assignee only | 32.5% | 32.5% | 455 | Partial |
| C "I'm on it" without RAW | 100% | 100% | 1400 | No |
| D claim+lease+RAW | 0% | 0% | 0 | Yes |
A: no coordination — dual-start is the baseline
Both machines see the same snapshot and both start. 40/40 mornings dual-start; 1400 wasted agent-minutes (35 min per duplicate start). Not a exotic fault injection — the baseline when heuristics say "go".
B: assignee only — still ~one third dual
"Assign then code" sounds like a lock. GitHub assignees behave more like a last-write hint. In a race window both sides can read an empty list and believe they won. The fixture uses a 35% dual-empty-read window; 13/40 mornings still dual-started (32.5%), wasting 455 minutes. Even when the server keeps a single assignee login, both agents already ran — the name is correct, the work is still duplicated.
Assignees are also soft socially: forgotten unassigns, shared logins, fine-grained tokens without Assignees write. Treating them as the only gate confuses etiquette with protocol.
C: "I'm on it" without read-after-write
The most common tribal fix. Both machines read empty comments, both post "I'm on it", both start. Both comments remain; nobody is the loser. Dual-start returns to 100%, waste matches A.
The bug is not "should we comment". It is write without read-back, and no forced abort when the read-back shows an earlier claim.
D: claim + lease + read-after-write
Short enough for AGENTS.md:
- Read labels: live
agent:claimedwith unexpired lease → refuse. - Write: add
agent:claimed+claim:machine-N, removeagent:ready; post a comment with<!-- agent-claim-v1 -->JSON (machine_id / session_id / issue / claimed_at / expires_at / nonce). - Immediately read back all claim comments; winner = earliest
claimed_at, thennonce. - If you are not the winner: drop your
claim:machine-N, mark the commentrace-yielded, do not start. - While holding:
heartbeat~every 30 minutes (default TTL 45m). - Abort or finish:
release. Dead expired lease:takeover-stalethen claim.
Across 40 mornings I also injected dual-write windows — both pass the "no live lease" check, both write, then each read-after-write. Result: dual-start 0%, duplicate PR 0%, waste 0. Losers always aborted. Separately: forcing expires_at into the past let machine-3 takeover-stale succeed; heartbeat renewed the lease. All on the fixture store.
The cost is not "one extra PR title"
In the toy repo, master apply_discount is a plain price * 0.9. Machine-1 adds clamp+round+discount_code(); machine-3 switches to flat ¥10 + member_tier(). git merge-tree yields a textbook changed in both on discount.py.
Worse than colliding empty PR titles: reviewers cannot Approve one and ignore the other — they must decide business semantics (percentage vs flat off on renewal). Agents do not schedule that meeting. Dual-start tax lands on machine-4's morning and on burned tokens.
Mechanism: why hints fail under concurrency
- GitHub Issues are not a lock service. Labels and comments become visible eventually; there is no transaction around your read+write. Two machines can both observe "empty".
- Assignee / verbal claim / branch names lack a loser protocol. Without "earlier claim found → I exit", a hint stays a hint.
- Agent sessions are short-lived. Without TTL+heartbeat, a machine that dies at 02:00 freezes the Issue; without stale takeover, a lease is worse than no coordination.
- Read-after-write is the minimal patch. You do not need etcd. The Issue comment thread is enough as a bulletin board — if you read after write, break ties by nonce, and make losers erase their own lease marks.
State machine: agent:ready → (claim+RAW) → agent:claimed → (PR / release) done; side paths race-yielded and stale→takeover-stale. Drop any edge and you fall back into A/C dual-start land.
Costs and when not to bother
- Two extra API round-trips per start (comment write + read-back). Negligible next to a 30-minute agent session.
- Label hygiene:
agent:ready/agent:claimed/claim:machine-N. Kit includeslabel_commands.sh. - TTL too short → false takeovers under heartbeat jitter; too long → dead sessions hog the Issue. 45m TTL / ~30m heartbeat is the lab default.
- Skip this when: one human one machine, Issues are always hand-assigned with no parallel sweeps, or the repo rarely opens two agent PRs a day. Social assignee norms then suffice.
- Does not help when: you want two parallel spikes on the same question — open child Issues; do not pretend to race one ticket.
- Not a review lease, not a Windows-fix lease, not WIP handoff. Different triggers: here "who may start"; there "who answers review threads / who fetches a failure scene / who continues an unfinished branch".
Boundaries with sibling posts
- /changes-requested-dead-agent-session/: Request changes after the authoring session died — a review-thread lease. Input here is an untouched Issue.
- /handoff-agent-task-between-machines/: Moving WIP across machines. Here both machines want to start from scratch.
- /windows-ci-failure-back-to-linux-agent/: Getting a failure scene back to a Linux agent. That lease is fix-rights, not Issue start-rights.
- /overnight-agent-pr-morning-triage/: Which overnight PRs to kill. This post asks why two colliding PRs appeared overnight.
- /parallel-agents-ports-databases/: Ports and databases. Runtime resources; here the resource is Issue semantics.
Copy-tomorrow minimum
- Create labels
agent:ready,agent:claimed,claim:machine-1..3(script in the kit). - Drop
claim_issue.pyinto repo tools;AGENTS.md: claim successfully before opening a branch; onok: false, pick another Issue. - Claim comments must carry
<!-- agent-claim-v1 -->JSON; ban bare "I'm on it" as a lock. - Default TTL 45m; heartbeat in-session;
releaseon abort;takeover-staleon expiry. - Morning triage: dual PRs on one Issue → check for claim comments first. Missing claims mean missing protocol, not "eager agents".
Rollout: --fixture on a toy store until claim / loser-abort / takeover are green; then --live printed gh commands, human-reviewed, then real Issues. Do not let seven machines write production labels on day one.
Honesty: what ran, what did not
Ran on this box:
simulate_race.py: A/B/C/D × 40 mornings; headline dual-start 100% / 32.5% / 100% / 0%; wasted minutes 1400 / 455 / 1400 / 0.claim_issue.py --fixture: successful claim, second machinealready_claimed, heartbeat, release, expiredtakeover-stale.- Toy git:
agent/m1-issue-88vsagent/m3-issue-88;git merge-tree→changed in bothondiscount.py.
Did not run:
- No live writes to Issue #88 on
shuizhengqi1/pagesor any product repo. - No seven-machine integration; dual-write windows were injected in the fixture.
--liveprintsghonly; lab default does not--execute.
Kit: two-agents-claim-same-issue-kit.tar.gz — claim_issue.py, simulate_race.py, results.json, AGENTS.md.snippet, label_commands.sh, toy conflict snapshots.
Smallest step today: next time an agent sweeps Issues, do not ask "did anyone say I'm on it?". Ask "is there a live agent:claimed, and after read-back am I the winner?". If not, the first line of code should not appear in your worktree.